Building Enterprise Data Architecture with Copernicus Data Space Ecosystem
Why the Copernicus Data Space Ecosystem Matters for Enterprise Data Architecture
Imagine having a huge amount of information about our Earth right at your fingertips. That is exactly what the Copernicus Data Space Ecosystem (CDSE) offers. It’s like a giant library for Earth observation data, and it’s free to use for everyone. In 2026, many businesses are looking for new ways to get and use this kind of important data. This data can help them make better choices.
The Copernicus Data Space Ecosystem is Europe’s main way to get data from its Sentinel satellites, which keep a close eye on our planet’s land, oceans, and air Copernicus Data Space Ecosystem | Europe’s eyes on Earth. It is designed as an open system where companies can easily get this data and even add their own tools or services. This means that instead of just getting raw data, enterprises can find, share, and reuse Earth observation data much more easily than before Ecosystem – Documentation.
This "data space" model changes how companies work with big datasets. It moves away from old ways of managing data, making it simpler to connect and use information.
For businesses, this means new chances to understand things better through advanced analytics definition what enterprise leaders must know for 2026. It also lets them use modern methods like creating a cloud native data platform that can handle a lot of information quickly. The CDSE is becoming the main spot for this kind of data, and it works like a public cloud service Copernicus Data Space Ecosystem establishes public cloud ….
In this article, we will look closely at what the Copernicus Data Space Ecosystem means for leaders like architects, Chief Technology Officers (CTOs), and those who lead data analytics teams. We will talk about important topics like:
- How to set up your technical systems (architecture patterns)
- Rules for managing data (governance)
- Making different systems work together (interoperability)
- How to use this data for smart insights and artificial intelligence (AI) projects, exploring enterprise AI adoption in 2026 a data backed roadmap for business leaders.
Understanding the CDSE is key to building strong enterprise data architecture that can use Earth observation data in powerful new ways.
Get clear daily AI updates from The AI Newsletter Worth Reading.
Understanding the Copernicus Data Space Ecosystem: Scope and Stakeholders
So, we know the Copernicus Data Space Ecosystem (CDSE) is a big treasure chest of Earth data. But who are the main players, and how do businesses actually use it? Let’s look closer at how this ecosystem works in 2026.
Who is Part of the Copernicus Data Space Ecosystem?
The CDSE is like a well-oiled machine with different parts working together.
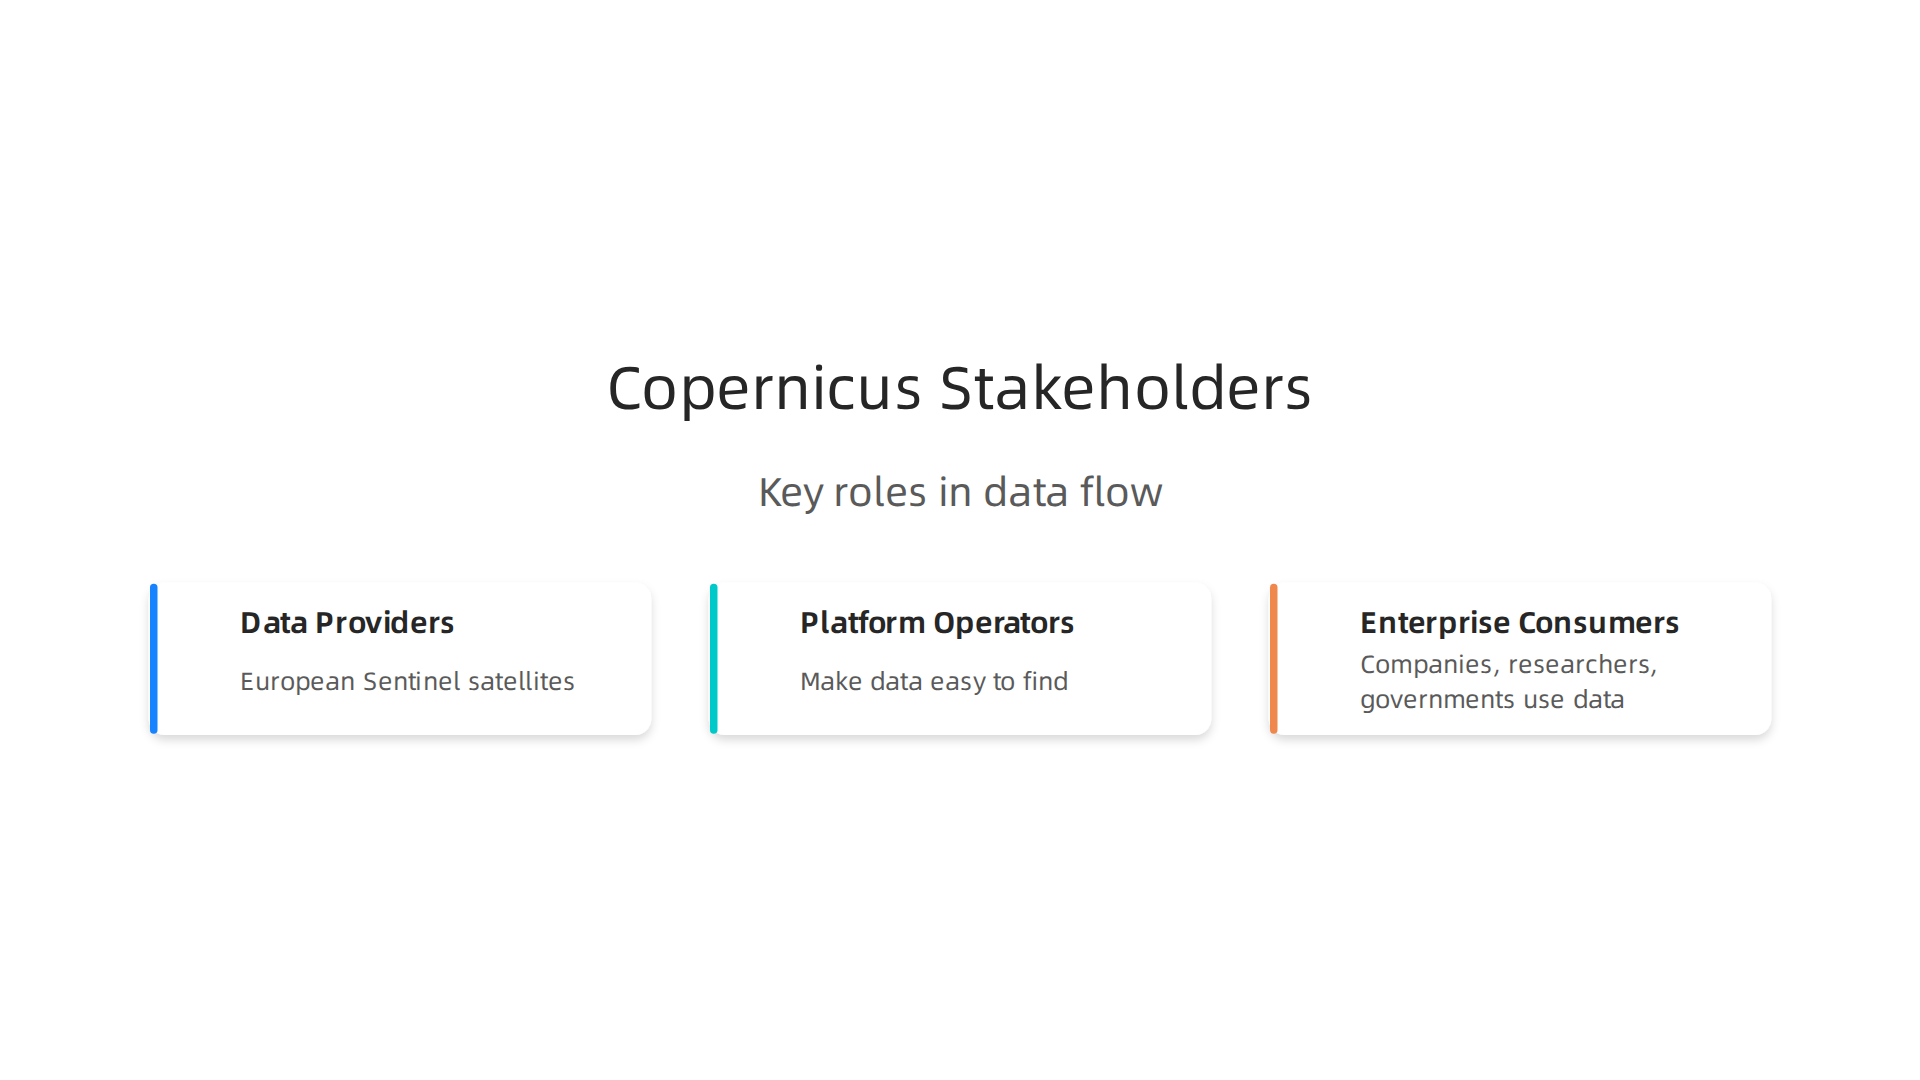
- Data Providers: At the very top are the European Sentinel satellites. These are like eyes in the sky, constantly collecting fresh information about our planet.
They gather data on land, oceans, and even the air we breathe Access to data – Copernicus. This raw data is the starting point for everything else.
- Platform Operators and Aggregators: This is where the Copernicus Data Space Ecosystem itself comes in. It takes all the raw data from the satellites and makes it easy to find and use. Think of it as the central hub. It also offers tools to process this data. Businesses don’t just get raw satellite images; they can also use services that help them make sense of the information About the Ecosystem. The CDSE is built as an open system, letting many different users and tools connect easily Copernicus Space Date Ecosystem Data access and processing ….
- Enterprise Consumers: This is where you come in! Companies, researchers, and government groups are the "consumers" of this data. They use the CDSE to get the Earth observation data for their own projects. They might use it for better business choices, new product ideas, or to study our environment.
How Businesses Connect: Practical Touchpoints
For enterprises, working with the Copernicus Data Space Ecosystem involves a few key things:
- Access Patterns: How do you get the data? The CDSE uses modern ways to let you grab information. This often means using APIs (Application Programming Interfaces). These are like special hooks that let your computer systems talk directly to the CDSE to request and pull data. This helps create a smooth data pipeline 2026 blueprint for building real-time reliable infrastructure for your business. The platform is designed to be flexible and allow users to bring their own datasets and applications.
- Licensing: Good news here! The data from the Copernicus Data Space Ecosystem is open and free to use for almost everyone. This means businesses don’t have to pay high fees just to get the information, which saves money and makes it easier to innovate. This open access is a big part of why the CDSE is so important for enterprise data architecture. It helps businesses reuse this valuable public data Publications Office.
- Metadata and Quality: When you’re dealing with so much data, knowing "what is data analytics" and understanding the data itself is very important. Each piece of data in the CDSE comes with "metadata." Think of metadata as a label that tells you what the data is, where it came from, and how it was collected. This helps you figure out if the data is good quality and right for your project. Knowing about this helps with better exploratory data analysis the critical first step for enterprise data science and good "data modeling" later on.
Understanding how the Copernicus Data Space Ecosystem (CDSE) works is one thing, but making the most of its vast data requires thinking about how you arrange your own company’s data. This means choosing the right way to build your data systems. In 2026, businesses often look at three main ways to organize their data: Federated Data Spaces, Data Mesh, and Data Fabric.
Each has its own good points and things to consider, especially when you’re dealing with lots of geospatial data from sources like the CDSE.
Core Architecture Patterns: Federated Data Spaces, Data Mesh, and Data Fabric
When you’re dealing with big amounts of information, knowing how to set up your data systems is key. Let’s break down some popular ways companies build their data foundations.
Federated Data Spaces: Working Together, Staying Separate
Imagine you have many different offices, and each office keeps its own files. A "federated data space" works a bit like that. Each part of your business, or even different companies, keeps its data separate but agrees on how to share certain information. The Copernicus Data Space Ecosystem itself is a great example of a federated approach on a grand scale, bringing together data from many sources while maintaining their individual control.
The main idea here is that data stays where it is, but rules are set up to let others access and use it. This often involves common standards for talking to each other, known as "interoperability." These rules help make sure everyone understands the data policies, often using things like the Open Digital Rights Language (ODRL) to spell out what you can and can’t do with the information Position Paper Semantic Interoperability In Data-Spaces. This setup is good for keeping control over your data while still sharing.
Data Mesh: Data as a Product, Owned by Teams
A Data Mesh is a newer way of thinking. Instead of one central data team, different teams within a company own and manage their own data. They treat their data like a product, making sure it’s easy for others to find, understand, and use. This means each team is responsible for the quality of their data and for making it available to others.
This approach often uses modern cloud data platforms and aims for a "cloud native data platform" setup. It helps avoid bottlenecks where everyone waits for one central team. It’s really useful when you have many different types of data and need to move fast. It also helps improve data governance by spreading the responsibility.
Data Fabric: A Unified View Over Everything
Think of a Data Fabric as a smart layer that sits on top of all your different data sources. It doesn’t move the data to one place. Instead, it connects everything together, no matter where the data lives. It uses smart tools, often powered by AI, to find, connect, understand, and manage data across your entire organization.
The goal of a Data Fabric is to give you a single, complete view of all your information, even if it’s stored in many different places and formats. This helps with complex "data modeling" and makes it easier to answer big questions. If you’re wondering what is data analytics at a deep level, a Data Fabric can provide the unified foundation needed for advanced analytics and AI projects. It also plays a big part in creating an AI-ready data environment for your business.
Choosing the Right Path for Geospatial Data
When working with Copernicus data and other geospatial information, choosing an architecture pattern depends on your company’s needs:
- Federated Data Spaces are great for sharing data between different organizations or when you need strict control over your own data, like when dealing with sensitive location information.
- Data Mesh works well if your company is large, has many different departments, and wants each team to take charge of its own data products. This can make processing huge amounts of satellite imagery and other geospatial data more agile.
- Data Fabric is best if you need a single, all-encompassing view of all your data, including Copernicus data, no matter where it’s stored. It helps you get insights quickly by connecting everything smartly.
Many companies in 2026 find that a mix of these ideas works best. The important thing is to pick an approach that helps you use data effectively, make good decisions, and grow your business. For leaders staying on top of the latest in enterprise technology, knowing these architectural patterns is a must.
Want to keep learning about how AI and technology are changing the enterprise world every day?
The AI Newsletter Worth Reading
After picking the right way to build your data systems, like Federated Data Spaces, Data Mesh, or Data Fabric, the next big step is making sure everyone plays by the rules. This is where governance, compliance, and trust come in. When you deal with lots of important information, especially from systems like the Copernicus Data Space Ecosystem, you need clear policies for sharing data and knowing who owns it.
Governance, Compliance, and Trust: Policies for Data Sharing and Sovereignty
Having good data is one thing. But making sure it’s used correctly and safely is another. This needs strong rules about how data is handled. In 2026, companies often look at these key parts of data governance:
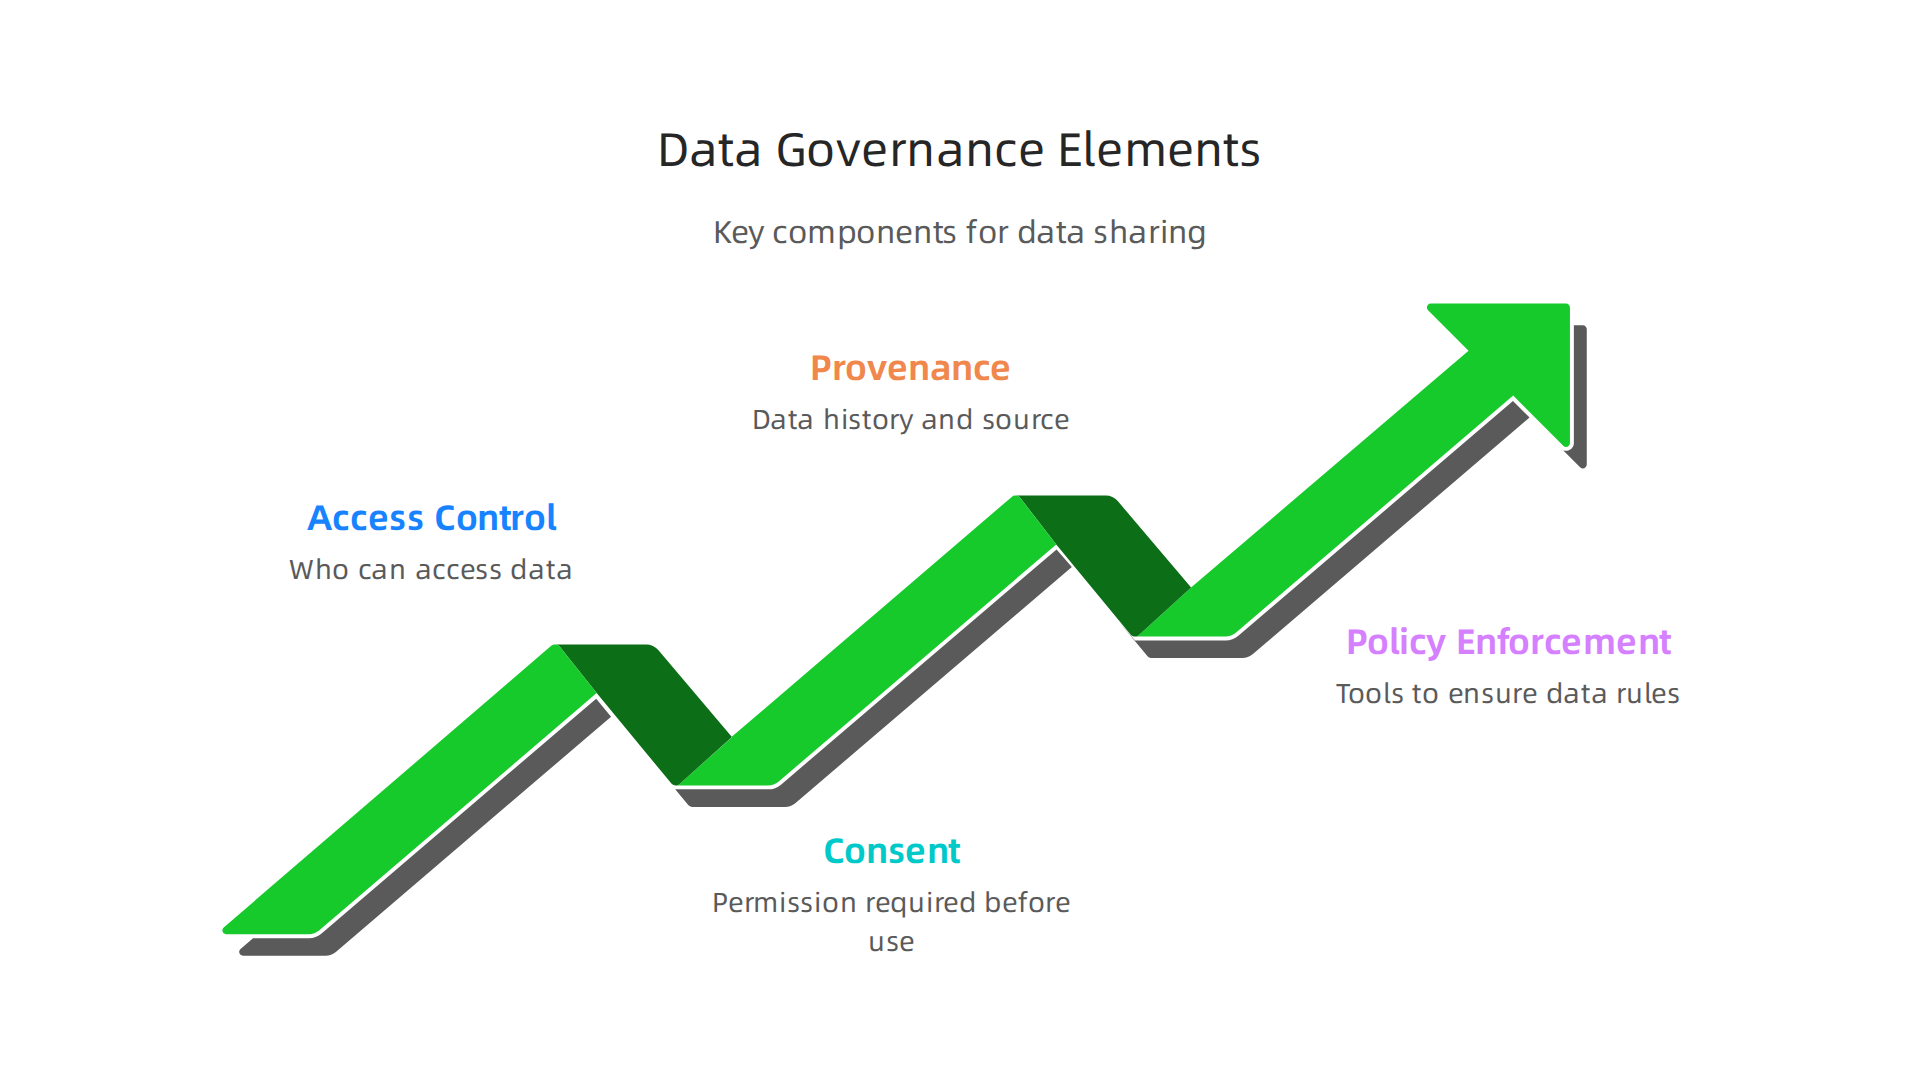
- Access Control: This is about who can see and use what data. Imagine a key card system for different rooms; only people with the right key can enter certain areas. For data, this means setting up digital permissions.
- Consent: Before using someone’s data, you often need their permission. This is especially true for personal data. It’s like asking for approval before borrowing something important.
- Provenance: This is knowing the history of your data. Where did it come from? Who touched it? What changes were made? Knowing the provenance helps you trust the data’s quality and source.
- Policy Enforcement: These are the tools and steps to make sure all the rules for data sharing and use are actually followed. It’s like having a system that checks everyone has a valid key card before entering a data room.
These rules help create a "trustworthy environment" for sharing data, especially in large systems like the Copernicus Data Space Ecosystem, which aims to provide open access to Earth observation data Copernicus Data Space Ecosystem | Europe’s eyes on Earth.
Rules from the Outside: GDPR and Data Sovereignty
Your choices about how to set up your data architecture are also shaped by bigger rules.
- GDPR (General Data Protection Regulation): This is a very important law in Europe that protects personal data. If your company works with data from people in Europe, you must follow GDPR rules. This means you need to be very careful about how you collect, store, and use personal information. It also affects how you handle things like consent and access control for that data Options for governance models for the European Health Data Space.
- Data Sovereignty: This idea means that data is subject to the laws of the country where it is stored. For example, if you store data about French citizens in a server in Germany, German and EU laws might apply. This is a big deal for international companies, as they need to think about where their data lives and the laws that govern it. Data spaces are designed to help with this by providing frameworks for data pooling and sharing across borders while respecting local laws Common European Data Spaces.
- Sector-Specific Compliance: Some industries have their own special rules. For example, healthcare data has very strict privacy rules, and financial data has security rules. When choosing a data architecture, you must make sure it meets these specific industry standards.
These external rules really impact how you design your data systems. A Data Fabric might need to be extra smart about sorting data by its origin and type to meet different legal needs. A Federated Data Space, by its very nature, helps maintain data sovereignty because data remains with its owner, who can then apply local rules.
Understanding these important layers of governance and compliance helps companies build secure, trusted, and legal data systems. It ensures that the valuable insights from data, like those from the Copernicus Data Space Ecosystem, can be used responsibly for the benefit of everyone. Thinking about these aspects is just as important as knowing how to evaluate insights and drive smarter cloud decisions.
After setting up strong rules for data, the next big step is making sure all your data systems can talk to each other. This is called interoperability. It means different parts of your data setup can understand and work with each other smoothly. Imagine trying to build a big puzzle where none of the pieces fit quite right; that’s what happens without good interoperability.
For companies in 2026, especially those dealing with lots of information like from the copernicus data space ecosystem, making sure data flows freely and correctly is key. This needs common ways of speaking, like using shared standards for data and tools that connect systems easily.
Speaking the Same Language: Standards, APIs, and Metadata
To make different data systems work together, we need a few important things:
- Metadata Standards: Metadata is like a label for your data. It describes what the data is, where it came from, and how it can be used. Think of a library where every book has a detailed card telling you its title, author, and topic. Good metadata helps you find and understand data. For example, the Open Digital Rights Language (ODRL) provides a common basis to formulate contract requirements for data sharing, making sure everyone knows the rules. Other common ways to describe data include Dublin Core, which helps with sharing information easily Semantic Interoperability solutions for data spaces.
- Data Descriptors: These are like detailed guides for specific types of data. For things like geospatial data (information about locations on Earth) or other observational data, special descriptors help everyone understand the format and meaning.
- API Contracts: An API (Application Programming Interface) is like a menu that tells you what services a system offers and how to order them. API contracts are the agreed-upon ways these systems will interact. A good example is the Dataspace Protocol for interoperable data sharing, which helps systems talk to each other safely and effectively. It means that a cloud native data platform, for instance, can connect with many different data sources without a lot of extra work.
These parts help build a reliable bridge between all your data, leading to better data modeling and overall data analytics.
How Data Moves Around: Integration Patterns
Once you have the right language and rules, you need ways to actually move data around. Here are some common ways companies connect their data systems in 2026:
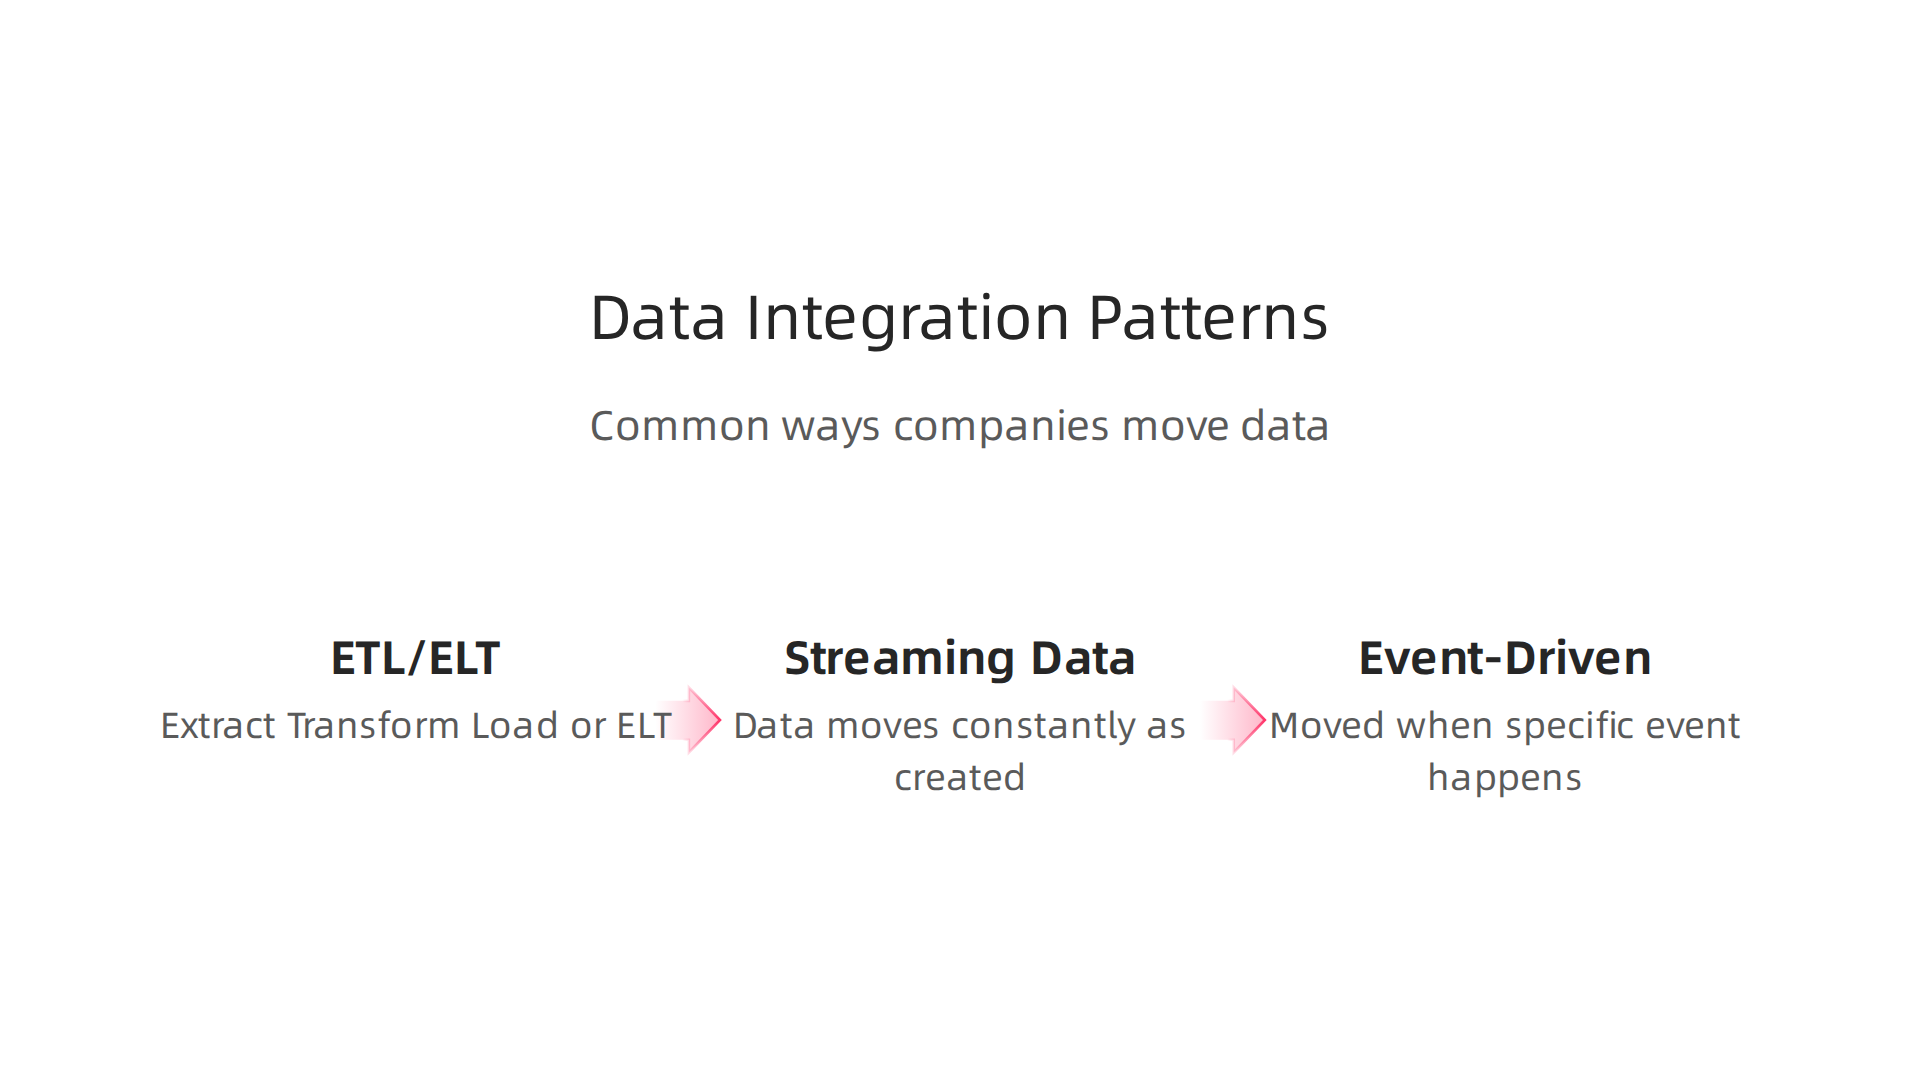
- ETL/ELT: These stand for Extract, Transform, Load (or Load, Transform). It’s like gathering ingredients (extract), chopping and mixing them (transform), and then putting them in a bowl (load). This is often used for moving large batches of data from one place to a data warehouse or a new cloud data platform.
- Streaming Data: This is like a continuous flow of water. Data moves constantly, as it’s created, from one system to another. This is really important for real-time information, like stock prices or sensor readings.
- Event-Driven Ingestion: This means data is moved only when something specific happens, like a "trigger." For example, when a new customer signs up, that "event" might trigger their data to be sent to a marketing system. This makes data flow more efficient.
By using these methods, companies can ensure that data from various sources, including complex systems like the copernicus data space ecosystem, can be brought together and used effectively. Understanding these ways of connecting data is crucial for anyone involved with enterprise technology.
The AI Newsletter Worth Reading
Stay informed about the fast-moving world of technology. Get clear daily AI updates from The AI Newsletter Worth Reading.
After setting up all those ways for data to move around, the next big step is to actually use that data for smart decisions. This is where analytics and AI come in.
Companies in 2026 are building special paths, or pipelines, to get the most out of their information, especially from huge sources like the copernicus data space ecosystem and other valuable datasets.
Analytics and AI Workflows: Building Scalable Pipelines on the Data Space
Creating pipelines for analytics is like setting up a factory line for insights. You can have lines for batch processing, which means working with large groups of data at once, like processing all sales data from the past month. Or you can have real-time inference, where data is looked at as it arrives, letting you make instant decisions, for example, detecting a problem in satellite imagery right away.
For complex data, such as that found in the copernicus data space ecosystem, which includes earth observation data, these pipelines must be very smart. They need to handle both big chunks of old data and new data coming in constantly. This helps companies figure out important things, like changes in weather patterns or land use. If you want to dive deeper into how these systems are built, check out our Data Pipeline 2026 Blueprint. Understanding Analytics Definition helps guide these efforts.
Handling AI Models: MLOps in a Distributed World
When it comes to using AI, especially machine learning (ML), we need a clear process to manage everything. This process is called MLOps, which stands for Machine Learning Operations. It’s like having a project manager for all your AI models, making sure they are built, tested, and used correctly. MLOps helps companies scale their AI efforts, making sure models are reliable and effective, as highlighted in one 2026 enterprise guide What Is MLOps? 2026 Enterprise Guide to Scaling.
Here are some important parts of MLOps in 2026:
- Model Training and Validation: This is where AI models learn from data. After they learn, they need to be tested (validated) to make sure they work well and give accurate results. For geospatial AI, like models using data from the
copernicus data space ecosystem, these steps are critical and need special attention to how data is managed, including sensor details and geographic coverage, as explained in discussions about MLOps for Geospatial AI Production Systems. - Versioning: Just like software, AI models change over time. Versioning means keeping track of different versions of your models and the data they were trained on. This is important for going back to an older version if a new one has problems or for understanding how a model has improved. Using a model registry helps with keeping things clear and repeatable Architecturally Significant MLOps Guidelines for ML Model.
- Provenance: This means knowing the full history of an AI model: where the data came from, who worked on it, and what changes were made. This is key for trust and fixing issues.
- Distributed Environment: Many companies now use distributed systems or
cloud data platformsto train and run AI models. This means the work is spread across many computers, often in acloud native data platformsetup, allowing for faster processing of huge datasets.
By carefully managing these steps through MLOps, businesses can ensure their AI models are not only powerful but also trustworthy and scalable within their copernicus data space ecosystem and across their entire data landscape.
After building and managing AI models with MLOps, the next big question is where these models actually live and do their work. This is all about how you deploy them. In 2026, companies think carefully about the best places to run their AI, especially when dealing with data that needs quick answers, like geospatial information from the copernicus data space ecosystem.
Where AI Models Live: Cloud, Edge, and Hybrid
When we talk about where AI models run, we often look at three main places:
- Cloud Deployment: This is like using a giant shared computer in the sky.
Cloud data platformsoffer huge computing power and storage, which is great for training big AI models or running tasks that don’t need instant results. It’s very flexible and can grow easily with your needs. However, sending all your data to the cloud and waiting for results can take time, especially for urgent tasks. You can learn more about making smart choices for your cloud setup in our guide on Cloud Research How to Evaluate Insights and Drive Smarter Cloud Decisions. - Edge Deployment: Imagine putting a small computer right where the data is made, like on a satellite or a sensor. This is called edge computing. It processes data very close to the source, which means much faster decisions and lower delays. For things like watching sudden changes in earth observation data from the
copernicus data space ecosystem, edge computing is super important because it provides answers when every second counts Edge Computing vs Cloud: Latency Impact. Processing data at the edge also helps save on bandwidth, as you don’t send all raw data to a faraway data center Edge Computing vs. Cloud Computing: A Strategic and …. - Hybrid Deployment: Many businesses in 2026 choose a mix of both. They use the power of
cloud data platformsfor heavy tasks like model training or long-term data storage, and they use edge computing for quick, local decisions. This helps them get the best of both worlds, balancing speed with the ability to handle huge amounts of data. This kind of setup often offers the best balance for both low-latency needs and scalable resources COMPARATIVE STUDY OF EDGE COMPUTING …. Choosing the right approach depends on what your application needs and what resources you have EXPLORING EDGE COMPUTING AND CLOUD ….
Keeping an Eye on Things: Observability and Monitoring
No matter where your AI models run, you need to make sure they are working correctly all the time. This is where "observability" and "monitoring" come in. It’s like having a control panel that shows you everything happening with your data and AI systems.
Here’s how it works:
- Logging: This means keeping a detailed diary of everything that happens. Every action, every error, every decision the AI makes is written down. This helps you understand what went wrong if a problem comes up.
- Tracing: When a piece of data moves through your system, from one step to the next, tracing lets you follow its exact path. This is helpful for seeing delays or issues in a
cloud native data platformsetup, for example. - Data Lineage: This shows the entire history of your data. You can see where data came from, how it was changed, and where it ended up. This is vital for trust and making sure your insights are accurate. Good data practices, including strong
data modeling, are key here. - Service Level Agreements (SLAs): These are promises about how well your data products will perform. For example, an SLA might say that your AI model will give an answer within 10 seconds 99% of the time. Monitoring helps you check if you are meeting these promises.
By setting up good monitoring and observability practices, you can quickly find and fix problems, ensure your AI is reliable, and make sure your business keeps getting good information. Want to stay updated on the latest in enterprise AI and cloud solutions?
The AI Newsletter Worth Reading
Summary
This article explains why the Copernicus Data Space Ecosystem (CDSE) matters for enterprise data architecture and how organizations can use satellite-derived Earth observation data effectively. It outlines the CDSE’s roles—data providers, platform operators, and enterprise consumers—and practical touchpoints such as API access, open licensing, and metadata quality. The piece compares three architecture patterns (federated data spaces, data mesh, and data fabric) and details governance needs like access control, provenance, GDPR, and data sovereignty. It also covers interoperability standards, common integration patterns, and building analytics and AI pipelines with MLOps, plus deployment trade-offs between cloud, edge, and hybrid setups. After reading, technology leaders will know how to design compliant, interoperable, and scalable systems that leverage CDSE data for analytics and AI.